 Zoho
Solutions
 Ecommerce
Development
 Web
Development
 AI
Solutions


- What AI-ready data architecture actually means
- Why data needs preparing before you scale generative AI
- Core components of an AI-ready architecture
- How to prepare enterprise data for generative AI: seven steps
- Not sure which data to prepare first?
- Securing and governing AI-ready data
- Choosing between common architecture patterns
- A worked example: an assistant for customer service reps
- How to tell whether your data is ready
- Mistakes that make AI data projects slower and costlier
- A phased roadmap for implementation
- Frequently Asked Questions
- What is an AI-ready data architecture?
- How do you prepare enterprise data for generative AI?
- What’s the difference between AI-ready data and clean data?
- Is a data warehouse enough for generative AI?
- What is RAG and why does it matter for enterprise data?
- Do I need a vector database to build AI applications?
- How do I keep AI data accurate and current?
- How long does it take to build an AI-ready data architecture?
- The bottom line
- Ready to prepare your enterprise data for AI?
A generative AI assistant can summarize a contract, answer a policy question, or check an order. It can only do that well with information it can find, understand, and is allowed to use. When product specs live in one system, customer records in another, and policies in a shared drive nobody has cleaned since 2022, even a strong model gives incomplete or confidently wrong answers.
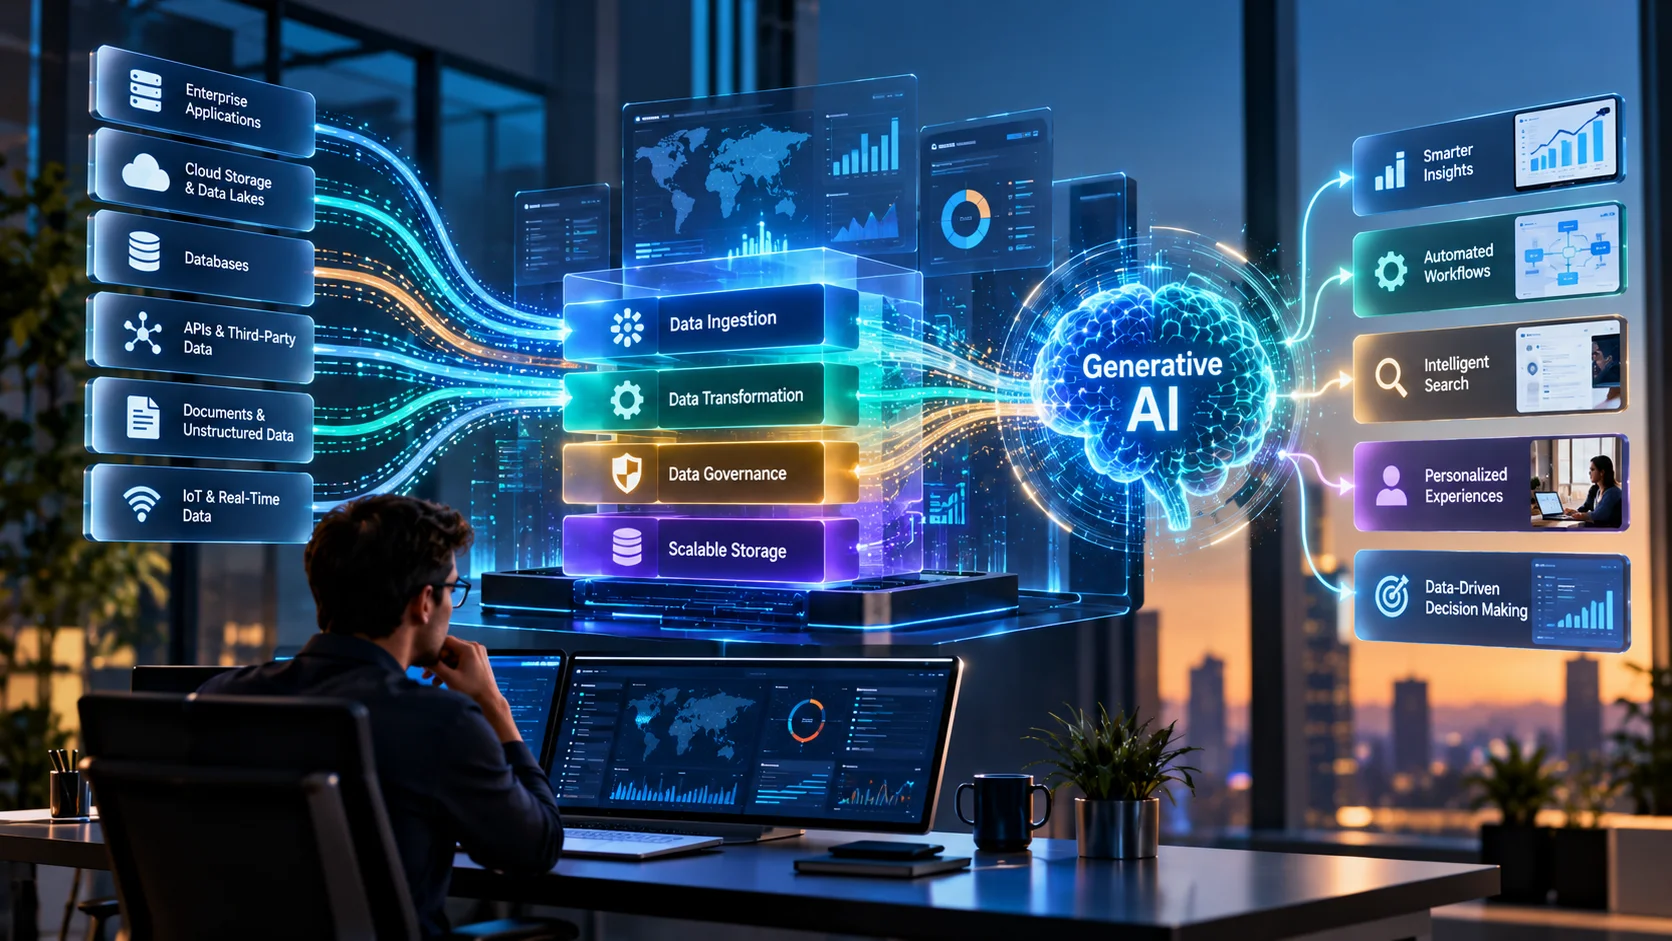
That’s the gap an AI-ready data architecture closes. It’s a structured way to collect, organize, govern, and deliver business information to AI applications. This guide walks through the components, a seven-step preparation process, security and governance, retrieval design, and a phased roadmap, plus an authority map and a permission test you won’t find in most overviews. If you’d rather scope this with a partner, Elsner’s data engineering and MLOps team starts from your use case, not a tool list.
Quick Answer
AI-ready data architecture is the combination of data sources, pipelines, storage, metadata, governance controls, and retrieval mechanisms that makes enterprise information accurate, relevant, current, and securely available to AI applications. Build it around one business use case at a time: define what the application must answer, name the authoritative source for every data element, fix the defects that would change those answers, enforce source permissions at retrieval, and test with realistic and adversarial questions before launch.
Research note: the architecture guidance here draws on Microsoft’s Azure retrieval-augmented generation design guide and the NIST AI Risk Management Framework. The worked example is a hypothetical scenario for illustration, not a client result. Tool choices depend on your environment, so treat the patterns as a starting point.
What AI-ready data architecture actually means
Traditional enterprise architecture was built for transactions, reporting, and dashboards. It assumes structured tables, scheduled queries, and people who know which report to open. Generative AI changes the demand. One question might need a paragraph from a PDF manual, a customer record, and today’s inventory, assembled in seconds, for a user whose permissions the system has to respect.
So data has to carry context, stay current enough for the task, and reach only authorized users and applications. Seven building blocks show up in almost every design.
- Data sources: business applications, databases, documents, APIs, and operational systems
- Ingestion and processing: pipelines that collect, validate, transform, and refresh information
- Storage: warehouses, lakes, lakehouses, document stores, and operational databases
- Metadata and semantics: what a dataset means, where it came from, and how fields map to business terms
- Governance and security: ownership, access, privacy, retention, and acceptable use
- Retrieval and delivery: search indexes, vector stores, APIs, and the logic that picks the right source
- Monitoring and evaluation: quality, freshness, retrieval performance, and reliability checks
None of this demands a brand-new stack. Many teams can build on the cloud platforms, databases, and security tooling they already run. The goal is making existing information dependable for AI, not adding complexity without a reason.
Why data needs preparing before you scale generative AI
Available data and usable data aren’t the same thing. A company might keep specifications in a content system, customers in a CRM, transactions in an ERP, procedures in shared documents, and metrics in a warehouse. Each works alone. An AI application usually needs several at once to answer a single question.
Skipping preparation shows up in five predictable ways.
- Conflicting versions: two systems hold different specs, and nothing says which one wins
- Missing context: “net revenue” means different things to finance and sales, so the model blends incompatible numbers
- Stale answers: last month’s inventory or an old HR policy gets presented with full confidence
- Uncontrolled access: a helpful assistant surfaces a confidential report to someone who shouldn’t see it
- Noisy retrieval: piles of irrelevant text raise cost and bury the passage that matters
Fixing these before launch is cheaper than fixing them as incidents. It also gives you a foundation the next AI project can reuse, instead of every team solving the same problems again.
Core components of an AI-ready architecture
The exact tools vary. The capabilities don’t. Think of five layers connected by clearly defined interfaces.
1. Data sources and connectors
Start by listing where the relevant information lives: ERP and CRM platforms, relational databases, file repositories, product catalogs, support tickets, contracts, APIs, and existing warehouses. For each source, record the owner, format, update frequency, access rules, and reliability. Decide whether data must arrive in real time, on a schedule, or through events. A reporting assistant may tolerate nightly syncs, while an inventory assistant can’t. Connectors should keep identifiers and permissions intact. For more on joining these systems, see our notes on connecting business intelligence to ERP and CRM systems.
2. Ingestion and processing pipelines
Pipelines move data in and clean it up on the way. Depending on the use case that means batch loads, event-driven ingestion, incremental updates, or change data capture. Useful capabilities include schema validation, duplicate detection, business-rule checks, retries, alerting, change tracking, and lineage. One rule matters more than the rest: if an update fails, the system should say so, not quietly serve data it knows is old. The line between data engineering and ML operations gets blurry here, which is why data engineering versus MLOps is worth understanding early.
3. Storage and organization
Not everything belongs in one repository. Pick storage by data shape, access pattern, and cost. Many teams already run a cloud warehouse such as the Snowflake cloud data platform, and extending it often beats buying a parallel system.
| Storage component | Primary purpose | Typical AI use |
|---|---|---|
| Data warehouse | Structured, modeled business data | Financial analysis and reporting |
| Data lake | Large raw and processed collections | Analytics and machine learning |
| Lakehouse | Scalable storage with managed analytics | Unified analytics and AI data prep |
| Operational database | Current transaction records | Customer, order, and inventory lookups |
| Document repository | Business files and unstructured content | Policy assistants and knowledge retrieval |
| Vector index | Similarity search over embeddings | Semantic search and RAG |
These pieces complement each other. One assistant might read policies from a document store, find passages through a vector index, and fetch order status from an operational API. Don’t move everything into one platform just because it’s marketed as an AI solution. Choose the smallest architecture you can maintain.
4. Metadata, definitions, and lineage
Metadata describes the data: names, field meanings, ownership, timestamps, classifications, and relationships. A field called customer_status might mean commercial standing in one app and case resolution in another. The architecture should make that difference obvious. Business definitions matter just as much. Active customer, net revenue, and eligible product need written meanings wherever consistency counts. Lineage records how data moves and changes, so you can trace a wrong answer back to its source.
5. Retrieval and delivery layer
This layer fetches the right information at request time. It may include search APIs, vector indexes, keyword search, business APIs, a semantic layer, or a RAG pipeline. Match the method to the task. Quarterly revenue questions need governed analytical queries. Policy questions suit document search. Live order status should come from the authoritative operational system. Treating every request as a vector-search problem is a common and costly shortcut.
How to prepare enterprise data for generative AI: seven steps
A defined sequence lets you improve the data environment without trying to modernize every system at once.
Step 1: Define the business use case
Begin with the problem, not the technology. Who will use the assistant, which decisions does it support, and what must it never do, such as reveal confidential records or invent missing policy? Then translate that into data requirements: which sources are authoritative, what has to stay current, and which questions it must answer. If the use case is still fuzzy, a short round of AI strategy consulting saves more than it costs.
Step 2: Audit existing data and infrastructure
Inventory the systems relevant to the use case and rate each for completeness, accuracy, freshness, ownership, permissions, duplication, and integration effort. Name an owner for every critical dataset. Don’t assume the central warehouse holds everything. Some essential facts live only in documents, operational APIs, or specialist tools.
Step 3: Fix quality where it changes the answer
AI-ready doesn’t mean perfect. It means fit for the purpose. Start with defects that would alter behavior: conflicting identifiers, inconsistent formats, duplicates, and invalid records. Where several records describe one customer, product, or supplier, link them with entity-resolution rules, and don’t auto-merge when the evidence is thin or a wrong match is costly. Master data tooling matters here, and our comparison of PIM versus MDM explains where each fits. Then set measurable indicators (completeness, uniqueness, validity, consistency, freshness) with thresholds, and route failures to a named team.
Step 4: Organize structured and unstructured data
Tables, PDFs, emails, manuals, and support chats need different handling. Structured data benefits from schemas and governed queries. Documents need text extraction, OCR where necessary, classification, and segmentation. Keep relationships intact: a spec stays tied to its product ID and version, and a policy excerpt keeps its title, section, date, and department. Don’t flatten everything to plain text, because headings, tables, and references carry meaning the model needs.
Step 5: Create a shared data model and an authority map
Define the entities your application uses, such as customers, products, orders, returns, and locations, and attach metadata for source, owner, version, effective date, sensitivity, and expiry. Then go one step further and write an authority map: for each data element, which system wins, how fresh it must be, and who settles disagreements. Here’s a sample.
| Data element | Authoritative source | Freshness limit | Conflict owner |
|---|---|---|---|
| Return policy | Policy repository, current version only | Updated within one day of approval | Customer operations lead |
| Order status | ERP, through its API | Live at request time | Fulfillment manager |
| Customer address | CRM | Within one hour of change | Sales operations |
| Product specification | Product information system | Updated at release | Product data owner |
A written authority map turns an arbitrary model decision into a documented rule. When two sources disagree, the application follows the map, and you can audit why.
Step 6: Select the integration and storage architecture
A typical build combines connectors, ingestion pipelines, governed storage, a catalog for discovery and lineage, search indexes or business APIs, an application layer that assembles context, and monitoring. Compare options on compatibility, security, latency, cost, scalability, team skills, and maintainability. If governance and storage already work, extend them. A clear logical design beats a long list of specialized tools.
Step 7: Build the retrieval pipeline
For questions over private documents, retrieval-augmented generation is the usual approach. It fetches relevant passages at query time and passes them to the model as context, so answers can reflect current or proprietary information without retraining. Microsoft’s RAG solution design and evaluation guide goes deeper on each stage. A document pipeline typically runs through these stages.
- Ingestion: collect approved documents and extract their contents
- Preparation: normalize text and drop artifacts, but keep structure
- Chunking: split into meaningful sections that still make sense alone
- Metadata: attach source, title, version, date, permissions, and section IDs
- Embedding and indexing: create vectors and store them with metadata, often alongside keyword search
- Retrieval: find passages, apply access limits, and assemble context
- Evaluation: check that evidence supports the answer and that citations are correct
One principle deserves repeating. RAG doesn’t guarantee accuracy. Retrieval can miss, source documents can be wrong, and a model can misread a good passage. Evaluate the data pipeline and the final answers separately.
Not sure which data to prepare first?
Elsner can audit your sources for one use case, draft the authority map, and recommend the smallest architecture that gets it into production.
Securing and governing AI-ready data
AI makes information easier to find and combine. That’s the value, and it’s also the risk, because a loose permission that once hid in a disconnected system can suddenly surface in a chat answer. The NIST AI Risk Management Framework is a useful reference for structuring these controls.
- Access controls: start with existing identity and access policies, and carry source-system permissions into retrieval instead of giving the application blanket access to a repository
- Classification: tag personal data, financial records, health information, trade secrets, and contracts, then apply masking, encryption, retention, and audit logging
- Data minimization: send the application what its task needs, not every field in the source
- Ownership: assign owners for datasets, definitions, quality thresholds, and access, and write down how errors and exposure incidents get handled
Where you can, enforce governance with technical controls. A policy that only lives in a document is harder to keep consistent than one backed by permissions, automated checks, and auditable workflows.
Run this permission test before launch
- Ask the assistant for restricted information as a user who shouldn’t have it, and confirm it refuses without hinting at the content
- Check cached answers and generated summaries, since a permitted answer cached for one user can leak to another
- Change a user’s role, then confirm the assistant’s access changes immediately, not at the next index rebuild
Choosing between common architecture patterns
No single pattern fits every use case. Choose by how the application needs to reach information.
| Pattern | Best suited for | Key consideration |
|---|---|---|
| Governed warehouse or lakehouse | Analytical queries and consolidated reporting | Semantic consistency and data quality |
| RAG with document retrieval | Knowledge assistants over internal documents | Retrieval quality, document structure, permissions |
| API-based retrieval | Current operational records and transactions | API reliability, latency, authorization |
| Hybrid retrieval | Documents, structured records, and systems together | Coordinating sources and reconciling results |
| Event-driven architecture | Applications needing frequent updates | Change handling, ordering, freshness |
| Domain-oriented data products | Large enterprises with many business domains | Clear ownership and shared standards |
Hybrid designs are common because enterprises rarely depend on one kind of information. Each added connection brings integration, security, and operating work, so use the simplest pattern that meets the requirement and add pieces only when something measurable demands it.
A worked example: an assistant for customer service reps
Picture a hypothetical company with customers in a CRM, orders in an ERP, product documentation in a content repository, and return policies in shared documents. First attempt: connect everything straight to a language model. The assistant quotes old return rules, trips over inconsistent product IDs, and shows data some employees shouldn’t see. An AI-ready approach fixes it in stages.
How the fix unfolds
- Authoritative sources: CRM for customers, ERP for live order status, the document repository for approved products and policies
- Preparation: product IDs standardized, obsolete policies pulled from active retrieval, documents tagged with owner, version, and effective date
- Retrieval paths: policies and documentation indexed for document search, while customer and order details come from authorized APIs
- Permissions: the assistant checks the employee’s authorization before retrieving restricted records
- Validation: test questions cover expired policies, conflicting records, missing information, and restricted data
- Monitoring: retrieval relevance, answer accuracy, freshness, latency, and access failures, traced back to the source, pipeline, or configuration that caused them
The lesson is simple. Feeding more data into a model doesn’t fix anything. Identifying the right information, preserving its meaning, enforcing permissions, and verifying behavior does. The same principles then carry to the next use case, as long as each one gets its own access rules and evaluation criteria.
How to tell whether your data is ready
Measure readiness against the intended application, not against a vague goal of perfect data. Pick indicators, set thresholds, and make results visible to whoever maintains the data.
| Metric | What it tells you |
|---|---|
| Completeness | Whether required fields and content exist |
| Accuracy and validity | Whether data matches trusted sources and defined rules |
| Consistency | Whether values and definitions agree across systems |
| Freshness | Whether updates land inside the required time window |
| Retrieval relevance and coverage | Whether the system finds useful evidence and doesn’t miss important material |
| Permission compliance | Whether users receive only what they’re authorized to see |
| Pipeline reliability and lineage coverage | Whether updates complete and information traces back to its source |
| Issue resolution time | How quickly detected problems get fixed |
Context sets the bar. A monthly report tolerates scheduled updates. A customer-facing inventory assistant needs far fresher data. A finance application needs strict numerical validation, while a policy assistant cares most about effective dates, document authority, and retrieval quality.
Mistakes that make AI data projects slower and costlier
Watch for these
- Connecting every source on day one. Begin with what one use case needs
- Assuming clean data is AI-ready. It also needs context, metadata, permissions, and a fitting retrieval method
- Using vector search for everything. Exact identifiers and calculations call for structured queries or APIs
- Ignoring source permissions, which turns a working pipeline into a security problem
- Treating retrieval as proof of accuracy. Relevant documents can still produce a wrong answer
- Letting indexes go stale after the initial cleanup
- Buying infrastructure before validating the need
- Skipping operational ownership for pipelines, quality incidents, and permission reviews
A phased roadmap for implementation
Phase 1: Assess and prioritize
Pick one use case, list its sources, users, security limits, and success criteria, and document the biggest readiness gaps.
Phase 2: Prepare and connect
Settle authoritative sources, fix critical quality problems, define metadata standards, and build the ingestion pipelines.
Phase 3: Build the AI data layer
Choose storage, search, retrieval, and API components, then add access controls, lineage, update procedures, and evaluation sets.
Phase 4: Test and validate
Run normal queries, difficult cases, conflicting records, stale data, missing evidence, and access restrictions. Score retrieval and generated answers separately.
Phase 5: Deploy and monitor
Launch with monitoring, incident procedures, and named owners, then track results against the original requirements.
Phase 6: Expand through reuse
Carry proven pipelines, governance rules, and metadata standards to the next use case, keeping application-specific permissions and evaluation.
Enterprises that want help with pipeline modernization, integration, or production infrastructure can start with Elsner’s data engineering and MLOps work, and teams ready to build the applications themselves can look at our AI and ML development practice.
Key takeaways
- AI-ready data architecture is built around a use case, not around a platform purchase.
- Write an authority map so every data element has one winning source, a freshness limit, and an owner.
- Match the access method to the question: governed queries, document retrieval, or live APIs.
- Carry source permissions into retrieval, and run the permission test before launch.
- RAG doesn’t guarantee accuracy, so evaluate the pipeline and the answers separately.
- Expand through reuse, one proven use case at a time.
Frequently Asked Questions
What is an AI-ready data architecture?
An AI-ready data architecture is a system of data sources, pipelines, storage, metadata, governance controls, and retrieval mechanisms that lets AI applications use accurate, relevant, and authorized information. Its design depends on the business use case and the application’s operating needs.
How do you prepare enterprise data for generative AI?
Define the use case, audit the relevant sources, fix quality problems that affect answers, organize structured and unstructured data, add metadata and an authority map, enforce access controls, and build the right retrieval path. Then test thoroughly before production.
What’s the difference between AI-ready data and clean data?
Clean data meets quality rules such as accuracy and completeness. AI-ready data also carries context, metadata, access controls, and a retrieval path suited to a specific application, plus the operational reliability to stay that way.
Is a data warehouse enough for generative AI?
Not always. A warehouse is excellent for structured analytics, but document-based assistants may also need unstructured content, semantic retrieval, or live operational APIs. Combine sources and access methods to fit the application.
What is RAG and why does it matter for enterprise data?
Retrieval-augmented generation fetches relevant enterprise information at query time and gives it to a language model as context. It can ground answers in current or proprietary data, but reliability still depends on data quality, retrieval, permissions, and evaluation.
Do I need a vector database to build AI applications?
No. A vector index supports semantic retrieval, but some applications work better with structured queries, keyword search, document search, or existing business APIs. Choose the method that fits the question being asked.
How do I keep AI data accurate and current?
Use source synchronization, validation checks, document versioning, freshness monitoring, and a clear response to failed updates. How often you refresh depends on how fast the information changes and what stale data would cost.
How long does it take to build an AI-ready data architecture?
It depends on the number of sources, current data quality, integration complexity, and security needs. A limited proof of concept takes far less effort than an enterprise-wide build, and a data audit gives the most reliable estimate.
The bottom line
A capable model can’t settle conflicting definitions, restore missing facts, or enforce your access policies on its own. The data foundation does that work. Prepare the information for one valuable use case, prove it under realistic conditions, and expand with the pieces that earn their place. That path costs less and breaks less than trying to fix everything first.
Ready to prepare your enterprise data for AI?
Bring one use case. Elsner will help you audit the data behind it, design the architecture, and plan a rollout you can measure.